Enterprise organisations generate and manage enormous amounts of information across documents, databases, customer relationship management (CRM) platforms, enterprise resource planning (ERP) systems, knowledge bases, and internal applications. However, accessing the right information at the right time remains a challenge.
Traditional search systems often struggle to understand the context behind complex questions. Meanwhile, large language models (LLMs) can generate useful responses but may produce inaccurate information when they lack access to an organisation's latest and most relevant business data.
This is where Enterprise RAG Architecture becomes valuable.
Retrieval-Augmented Generation (RAG) connects large language models with trusted enterprise information. Instead of relying only on their training data, AI applications retrieve relevant information from approved knowledge sources and use it to generate context-aware responses.
However, building an enterprise-ready RAG solution involves more than connecting a vector database to an LLM. Organisations must consider data ingestion, document processing, retrieval quality, security, access permissions, evaluation, monitoring, and scalability.
This guide explains how enterprise RAG architecture works, its core components, implementation approaches, technology choices, security considerations, and best practices for building production-ready RAG applications.
What Is Enterprise RAG Architecture?
Enterprise RAG architecture is the technical framework used to connect large language models with an organisation's internal and external knowledge sources.
It allows an AI application to retrieve relevant information from business documents, databases, applications, and other approved repositories before generating a response.
For example, imagine an employee asking an internal AI assistant:
"What is our current process for approving international vendor payments?"
A general-purpose language model may not know the organisation's internal payment policy. An enterprise RAG application can search approved finance policies, retrieve the relevant approval requirements, and generate an answer based on those documents.
The response can also include references to the source documents, allowing employees to verify the information.
A typical enterprise RAG system combines:
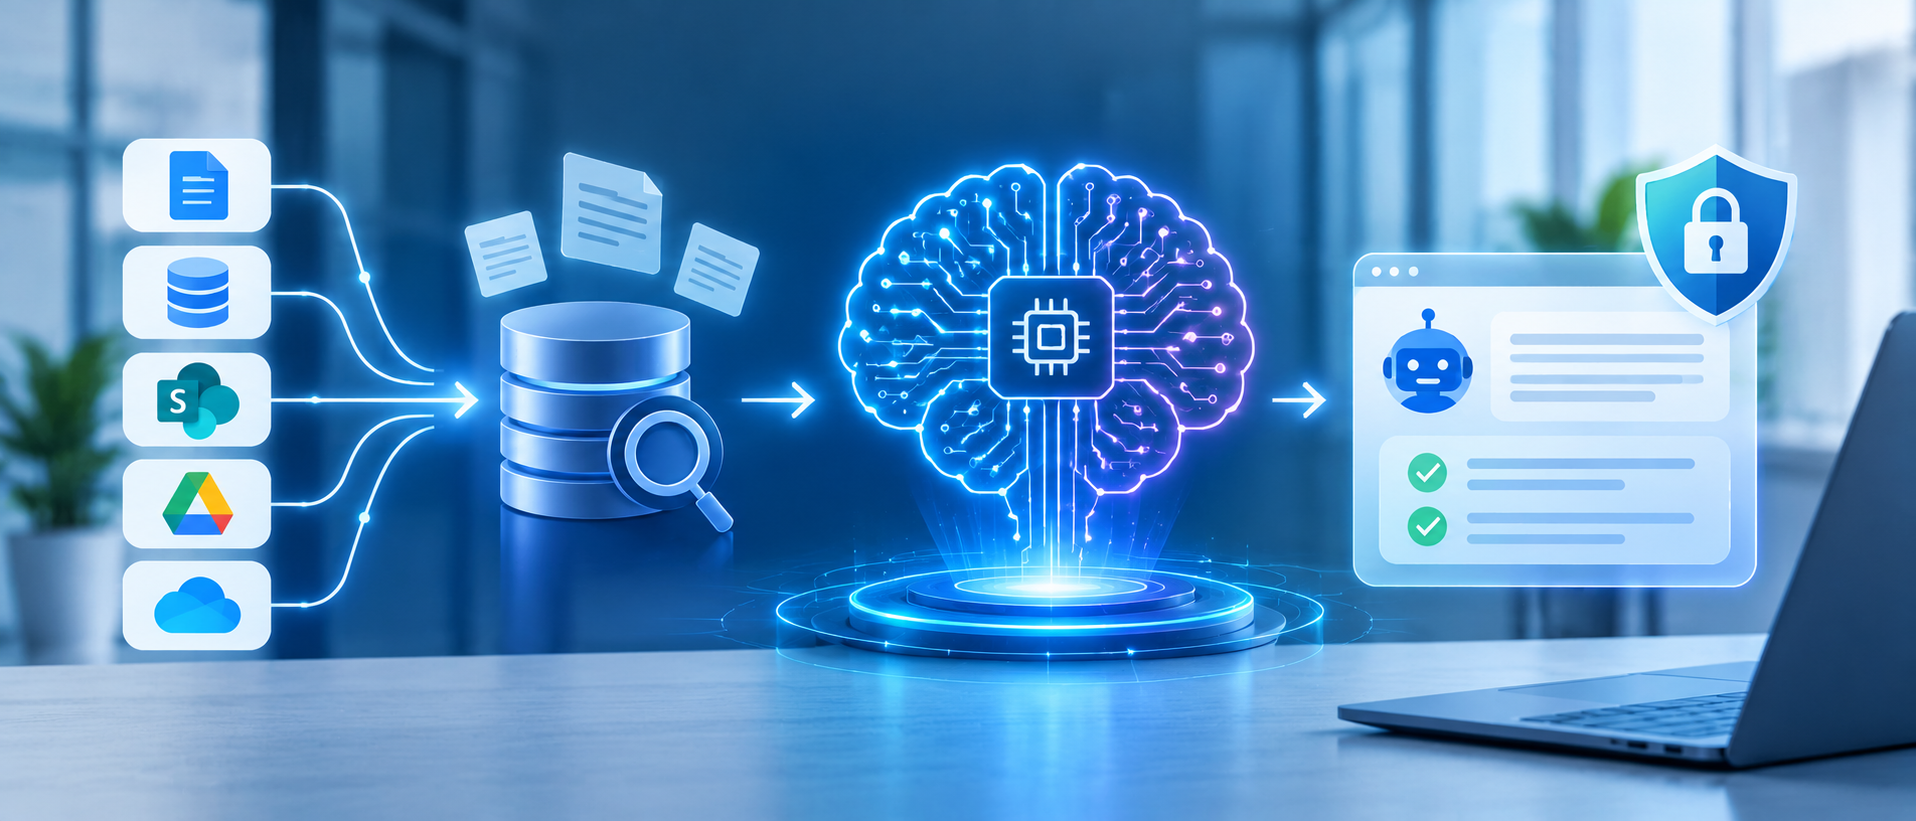
- Enterprise data sources such as SharePoint, Google Drive, databases, CRM, and ERP platforms.
- Data ingestion and document processing pipelines.
- Text chunking and metadata extraction.
- Embedding models and vector indexes.
- Keyword and semantic search.
- Retrieval and reranking components.
- Large language models for response generation.
- Security, access control, and monitoring systems.
The objective is to make enterprise AI applications more relevant, context-aware, secure, and useful for real business workflows.
How Does an Enterprise RAG System Work?
An enterprise RAG system generally operates through two connected workflows:
- Data ingestion pipeline: Prepares organisational information so it can be searched.
- Query and generation pipeline: Retrieves relevant information and uses it to generate an answer.
Separating these workflows makes the architecture easier to maintain, scale, and troubleshoot.
1. Data ingestion from enterprise sources
The first stage collects information from the systems where an organisation stores its knowledge.
Common data sources include:
- SharePoint and Microsoft 365.
- Google Workspace.
- Internal databases and data warehouses.
- CRM platforms such as Salesforce.
- ERP applications.
- Confluence and other knowledge management platforms.
- PDF documents, Word files, spreadsheets, and technical manuals.
- Internal APIs and business applications.
The ingestion layer should support the required source formats and authentication methods. It should also track document ownership, permissions, update timestamps, and source identifiers.
This information becomes important when the system needs to update its index or determine whether a user can access a particular document.
2. Document processing and data preparation
Enterprise information is rarely stored in one consistent format. Documents may contain paragraphs, tables, images, scanned pages, headings, metadata, and structured records.
Before indexing, the system must extract and standardise this information.
Typical processing activities include:
- Extracting text from supported document formats.
- Applying OCR to scanned documents where required.
- Removing irrelevant formatting and duplicate content.
- Detecting document language.
- Identifying headings, sections, and tables.
- Extracting metadata such as document type, department, owner, and update date.
- Applying data classification and sensitive information handling rules.
For example, a finance policy containing approval thresholds should retain the relationship between each threshold and its corresponding approval requirement. Simply extracting all the text without preserving its structure can make later retrieval less accurate.
3. Text chunking and metadata enrichment
Large documents are divided into smaller sections called chunks. These chunks allow the retrieval system to identify specific information instead of processing an entire document for every question.
Chunking is one of the most important decisions in RAG application development.
If chunks are too large, they may contain unrelated information. If they are too small, important context may be separated from the passage that explains it.
Different document types require different chunking strategies.
| Document type | Recommended chunking approach |
|---|---|
| Company policies | Split by headings and policy sections |
| Contracts | Split by clauses and retain clause references |
| Technical documentation | Keep explanations and related code examples together |
| Customer support tickets | Group conversations by issue and resolution |
| Product catalogues | Preserve product attributes and descriptions |
| Spreadsheets | Retain meaningful row and column relationships |
| Research reports | Split by sections while preserving headings and source details |
Each chunk should also include useful metadata.
For example:
{
  "document_id": "policy_102",
  "document_title": "Vendor Payment Policy",
  "department": "Finance",
  "section": "International Payments",
  "access_group": "finance_team",
  "last_updated": "2026-10-15",
  "chunk_id": "policy_102_04"
}
Metadata makes it possible to filter search results by department, document type, access permissions, and other business requirements.
4. Embedding generation and vector indexing
After document processing and chunking, the system converts text into numerical representations called embeddings.
Embeddings capture semantic relationships between pieces of information. This allows a search system to identify content that is conceptually related to a question, even when the wording is different.
For example, an employee searching for "parental leave eligibility" may retrieve a document section titled "Family Leave Policy."
The embedding model converts each chunk into a vector, which is then stored in a vector database or search platform.
Common technology choices include:
- Pinecone.
- Weaviate.
- Chroma.
- PostgreSQL with pgvector.
- Elasticsearch.
- Managed cloud search services.
The right choice depends on data volume, search requirements, filtering capabilities, infrastructure, operational expertise, and security needs.
Importantly, vector storage is not the only requirement. Enterprise systems also need document identifiers, metadata, permission information, and a way to update or remove outdated records.
5. Query processing and retrieval
When a user submits a question, the application processes the query and searches the indexed knowledge base.
A basic retrieval workflow may include:
- Authenticate the user.
- Identify the user's access permissions.
- Normalise or rewrite the query where appropriate.
- Generate an embedding for semantic search.
- Run keyword, vector, or hybrid retrieval.
- Apply access and metadata filters.
- Return relevant document chunks.
For enterprise applications, hybrid search is often worth evaluating because it combines keyword matching with semantic similarity.
Keyword search can be particularly useful for exact product codes, contract identifiers, technical terms, and policy references. Vector search can help when users describe a concept differently from the wording in the source document.
Combining them can improve the range of relevant information retrieved.
6. Reranking and context selection
Initial retrieval may return several potentially relevant passages, but not all of them will answer the user's question.
A reranking component evaluates the retrieved results against the query and moves the most useful passages higher in the result list.
For example, a search for "Who can approve a high-value international payment?" might return:
- A general payment policy.
- A vendor onboarding guide.
- An international payment procedure.
- An employee expense policy.
A reranker can prioritise the passages that directly describe approval authority.
The system then selects the most relevant content for the language model. This helps reduce irrelevant context and can improve response quality.
Reranking also introduces additional processing time and cost, so it should be evaluated against the accuracy and latency requirements of the application.
7. LLM response generation
Once relevant information has been retrieved, the application passes the selected context and the user's question to an LLM.
The prompt should clearly instruct the model to:
- Answer using the supplied evidence.
- Avoid inventing information not supported by the retrieved sources.
- Cite the relevant source documents.
- State when the available information is insufficient.
- Follow the application's response and safety rules.
The model generates the final answer using the retrieved enterprise information.
A well-designed application should not treat a fluent answer as proof of correctness. Responses still need to be evaluated, particularly when they influence financial, legal, operational, or other high-impact decisions.
Enterprise RAG Architecture: End-to-End Workflow
The following simplified architecture illustrates how the ingestion and query workflows connect.
                 ENTERPRISE DATA SOURCES
       SharePoint | CRM | ERP | PDFs | Databases
                         |
                         v
                 DATA INGESTION
            Connectors and authentication
                         |
                         v
                DOCUMENT PROCESSING
             Extraction | OCR | Cleaning
                         |
                         v
                 TEXT CHUNKING
              Structure and metadata
                         |
                         v
                EMBEDDING MODEL
                         |
                         v
               SEARCH INDEX / STORE
             Vector + Keyword Index
                         |
             -------------------------
             |                       |
             |     QUERY WORKFLOW    |
             |                       |
             v                       |
          USER QUESTION              |
             |                       |
             v                       |
       AUTHENTICATION & ACL           |
             |                       |
             v                       |
       QUERY PROCESSING               |
             |                       |
             v                       |
       HYBRID RETRIEVAL --------------
             |
             v
          RERANKING
             |
             v
       CONTEXT ASSEMBLY
             |
             v
       LARGE LANGUAGE MODEL
             |
             v
       ANSWER + CITATIONS
             |
             v
       MONITORING & FEEDBACK
The diagram represents a conceptual design. The actual implementation may use managed cloud services, open-source components, or a combination of both.
Core Components of Enterprise RAG Architecture
A production-ready RAG solution requires multiple components working together. Each component has a specific responsibility, and weaknesses in one stage can affect the quality of the final response.
| Component | Primary responsibility | Business value |
|---|---|---|
| Data connectors | Access approved enterprise sources | Connects existing business information |
| Processing pipeline | Extracts and cleans content | Improves data consistency |
| Chunking engine | Divides content into useful sections | Preserves relevant context |
| Embedding model | Converts text into vectors | Enables semantic search |
| Vector database | Stores and searches embeddings | Supports similarity-based retrieval |
| Keyword search | Finds exact terms and identifiers | Improves precise matching |
| Reranker | Reorders retrieved passages | Improves relevance |
| LLM | Generates natural language responses | Makes information easier to use |
| Access control | Enforces user permissions | Protects confidential information |
| Evaluation and monitoring | Measures quality and performance | Supports continuous improvement |
The architecture should be selected around the application's requirements rather than the popularity of individual tools.
Choosing the Right Retrieval Strategy for Enterprise AI
Retrieval quality has a direct impact on the usefulness of an enterprise RAG application.
A system may use one retrieval technique or combine several approaches depending on the nature of the information and user queries.
Vector search
Vector search uses embeddings to identify semantically similar content.
It is useful when users ask questions in natural language or use different terminology from the source documents.
For example, a user asking "How can staff request time away from work?" may retrieve a policy section titled "Employee Leave Procedure."
Keyword search
Keyword search identifies documents containing specific words, phrases, or identifiers.
It is particularly useful for:
- Product codes.
- Contract numbers.
- Employee IDs.
- Technical error messages.
- Policy references.
- Exact names and terminology.
Hybrid search
Hybrid search combines keyword search and vector search to retrieve information using both lexical and semantic relevance.
This is often a strong starting point for enterprise knowledge systems because organisational documents contain both natural language and exact identifiers.
Reranking
Reranking evaluates the initial search results and prioritises passages that are more relevant to the user's question.
It is especially useful when the knowledge base contains a large number of similar documents or when the initial retrieval stage returns too many candidates.
| Retrieval approach | Best suited for | Main consideration |
|---|---|---|
| Vector search | Conceptual and natural-language questions | Depends on embedding and index quality |
| Keyword search | Exact terms, names, and identifiers | May miss differently worded content |
| Hybrid search | Mixed enterprise information needs | Requires ranking configuration |
| Reranking | Improving relevance among retrieved results | Adds latency and processing cost |
Microsoft's RAG information retrieval guidance explains how keyword, vector, hybrid search, and reranking can be configured and evaluated.
Advanced Enterprise RAG Architecture Patterns
Not every enterprise application needs the same retrieval design. A straightforward internal knowledge assistant may work with a conventional RAG pipeline, while complex workflows may require additional retrieval and reasoning capabilities.
1. Classic RAG
Classic RAG follows a relatively direct workflow:
User question → Retrieval → Context selection → LLM generation → Answer.
It is suitable for applications such as:
- Internal policy assistants.
- Product documentation search.
- Employee knowledge portals.
- Customer support knowledge bases.
It is often a practical starting point when requirements are clearly defined and response times matter.
2. Hybrid RAG
Hybrid RAG combines vector and keyword search, often followed by reranking.
It is useful when enterprise content contains technical terminology, identifiers, and natural-language descriptions.
For example, an engineering assistant may need to find a specific error code while also understanding the broader troubleshooting question.
3. Agentic RAG
Agentic RAG introduces an orchestration layer that can decide how to retrieve information.
Instead of executing one fixed search, an AI agent may:
- Break a complex question into smaller queries.
- Search multiple knowledge sources.
- Select an appropriate retrieval strategy.
- Gather additional information when required.
- Combine retrieved evidence before generating a response.
Consider an employee asking:
"Compare the latest travel reimbursement policy with the previous version and explain what has changed."
The application may need to identify both versions, retrieve their relevant sections, compare the content, and produce a structured summary.
Agentic retrieval can help with these multi-step questions, but it also introduces more complexity, latency, and opportunities for failure. It should be used when the business problem genuinely requires dynamic retrieval.
4. GraphRAG
GraphRAG combines retrieval with knowledge graphs that represent entities and their relationships.
Traditional vector search is useful for retrieving similar passages. However, some enterprise questions require understanding how different entities are connected.
For example:
"Which suppliers are connected to projects managed by our European operations team?"
Answering this may require relationships between suppliers, projects, departments, and locations.
A knowledge graph can represent these relationships explicitly, while retrieval provides supporting document evidence.
Graph-based retrieval can be useful for complex, relationship-heavy information, but it requires additional work to build and maintain the graph.
5. Multimodal RAG
Enterprise information is not limited to text. It can include scanned documents, diagrams, charts, product images, audio, and video.
Multimodal RAG extends retrieval to these different information types.
For example, a manufacturing assistant may need to retrieve information from equipment manuals, technical diagrams, and inspection images.
The processing architecture must be able to extract and represent the relevant information before it can be searched.
Enterprise RAG Security: Protecting Sensitive Business Data
Security is one of the most important considerations in enterprise RAG architecture.
A knowledge assistant may have access to confidential HR policies, financial reports, customer records, contracts, and internal technical documentation. If the retrieval layer does not enforce permissions correctly, users could receive information they are not authorised to access.
Security must therefore be built into the entire pipeline.
Role-based access control
The application should authenticate users and enforce access permissions before retrieving information.
For example:
- HR employees may access approved HR documents.
- Finance employees may access finance policies.
- Engineering teams may access technical documentation.
- General employees may access company-wide policies.
Permissions should be enforced at retrieval time, not simply after the model has received the documents.
Document-level security
Each indexed document or chunk should retain the appropriate access metadata.
The retrieval service should filter results according to the user's identity, group membership, tenant, and document permissions.
Permission changes must also be reflected in the index. A user who loses access to a document should not continue receiving its content through an outdated search index.
Data privacy and encryption
Enterprise RAG systems should consider:
- Encryption in transit and at rest.
- Secure authentication and secret management.
- Data retention and deletion requirements.
- Personal and sensitive information handling.
- Tenant isolation for multi-customer applications.
- Approved model and hosting environments.
- Audit logging and access monitoring.
Prompt injection and malicious documents
Documents retrieved from external or internal sources should be treated as untrusted content.
A malicious document could contain instructions designed to manipulate the language model. The application should clearly separate retrieved content from system instructions and should not allow document text to override security policies.
Additional controls include input validation, output validation, restricted tool permissions, and testing against prompt injection attempts.
The OWASP RAG Security Cheat Sheet provides practical guidance on securing ingestion, embeddings, retrieval, generation, and downstream integrations.
For broader governance, organisations can also refer to the NIST Generative AI Risk Management Framework profile.
How to Evaluate Enterprise RAG Performance
A RAG system should not be considered production-ready simply because it generates convincing answers during a demonstration.
Organisations need a repeatable evaluation process that measures whether the system retrieves the right evidence and generates responses supported by that evidence.
Important RAG evaluation metrics
| Metric | What it measures | Why it matters |
|---|---|---|
| Retrieval precision | How many retrieved results are relevant | Helps identify irrelevant context |
| Retrieval recall | How much of the relevant information is retrieved | Helps identify missing evidence |
| Context relevance | Whether retrieved content matches the question | Measures usefulness of the context |
| Faithfulness | Whether the answer is supported by retrieved evidence | Helps identify unsupported claims |
| Answer relevance | Whether the response addresses the question | Measures usefulness to the user |
| Latency | Time taken to generate a response | Affects user experience |
| Cost per query | Processing and model cost for a request | Supports cost management |
| Access-control accuracy | Whether retrieval respects permissions | Helps prevent data exposure |
Build a representative evaluation dataset
Start by collecting realistic questions from the business teams that will use the application.
For each question, record:
- The expected answer or key facts.
- The documents that should support the answer.
- The user role or access group.
- Whether the system should answer or abstain.
- Any important constraints.
Test the application using these questions after changes to chunking, embeddings, retrieval settings, prompts, or models.
Human reviewers should also examine high-impact responses. Automated evaluation is useful, but it does not eliminate the need for business and domain validation.
Practical Implementation: A Simple Python RAG Retrieval Example
The following example illustrates the basic retrieval stage of a RAG application using a Python-based search client.
It is an architectural example rather than a complete production implementation. The actual embedding model, search client, authentication, index configuration, and permissions must be implemented for the selected technology stack.
def retrieve_context(question, user_context, search_client, embedding_model):
    # Authenticate and obtain the user's authorised scope
    allowed_groups = user_context["allowed_groups"]

    # Generate a query embedding using the same model
    # used to create the document embeddings
    query_vector = embedding_model.embed_query(question)

    # Search using semantic similarity and access filters
    results = search_client.hybrid_search(
        query=question,
        vector=query_vector,
        filters={
            "access_group": {"$in": allowed_groups}
        },
        top_k=10
    )

    # Return relevant content and source information
    context = []

    for result in results:
        context.append({
            "content": result["content"],
            "source": result["document_title"],
            "section": result.get("section")
        })

    return context
The example highlights an important architectural principle: user permissions must influence retrieval. In a real system, access checks should be enforced by trusted backend services and the search platform, not by relying on the LLM to decide which documents a user may see.
A complete implementation would also include reranking, context limits, citation mapping, error handling, logging, and response evaluation.
Technology Stack for Enterprise RAG Development
Selecting the right technology stack depends on the organisation's data environment, infrastructure, security requirements, and development capabilities.
The following are examples of commonly used technology categories and tools.
| Technology layer | Example tools | Purpose |
|---|---|---|
| Programming | Python, TypeScript | Application and pipeline development |
| LLMs | OpenAI, Azure OpenAI, Gemini, Claude, Llama | Response generation |
| Embeddings | OpenAI embedding models, cloud embedding services, open-source models | Semantic representation |
| Vector storage | Pinecone, Weaviate, Chroma, pgvector | Embedding storage and retrieval |
| Search | Elasticsearch, Azure AI Search, OpenSearch | Keyword and hybrid search |
| Orchestration | LangChain, LlamaIndex, LangGraph, Semantic Kernel | Workflow and retrieval orchestration |
| Data processing | Python libraries, OCR services, ETL tools | Document extraction and preparation |
| Infrastructure | AWS, Microsoft Azure, Google Cloud, Kubernetes | Hosting and deployment |
| Evaluation and monitoring | MLflow, LangSmith, custom evaluation pipelines | Quality and operational monitoring |
These tools are examples, not a mandatory combination. A managed cloud search service may reduce operational overhead, while a self-managed stack may offer greater control over deployment and configuration.
Google Cloud also publishes RAG reference architectures covering different infrastructure and deployment approaches.
Common Enterprise RAG Implementation Challenges
Even well-designed RAG systems can encounter problems when they move from experimentation to production.
Understanding these challenges early helps organisations avoid expensive redesigns.
Poor document quality
Incomplete, outdated, duplicated, or poorly structured documents can reduce retrieval quality.
How to address it: Establish data ownership, document validation, duplicate detection, and a process for updating or removing outdated content.
Incorrect chunking strategies
Splitting documents without considering their structure can separate important context.
How to address it: Use document-aware chunking and test different chunk sizes and overlap settings against representative questions.
Weak retrieval relevance
A system may retrieve content that is related to the topic but does not answer the actual question.
How to address it: Evaluate hybrid search, query rewriting, metadata filters, and reranking.
Data access and permission failures
An index may contain documents from different departments with different confidentiality requirements.
How to address it: Preserve access metadata, enforce permissions at query time, and test with users from different access groups.
Hallucinated or unsupported responses
An LLM may generate information that is not present in the retrieved context.
How to address it: Use evidence-based prompts, source citations, answer validation, and an explicit abstention path when supporting information is insufficient.
Increasing operational costs
Large indexes, frequent embedding updates, reranking, and high model usage can increase operating expenses.
How to address it: Monitor cost per query, cache appropriate results, optimise retrieval depth, and select models according to task complexity.
Stale enterprise information
A knowledge assistant can provide outdated answers if documents are changed but the index is not updated.
How to address it: Use scheduled or event-driven indexing, document version tracking, deletion workflows, and freshness monitoring.
Enterprise RAG Architecture Best Practices
For a reliable production implementation, organisations should follow a structured approach.
- Start with a specific business problem. Select a measurable use case such as internal policy search, support knowledge retrieval, or document assistance.
- Assess data readiness. Identify information sources, ownership, quality, access rules, and update frequency.
- Design the ingestion pipeline. Build reliable connectors and processing workflows for the required data sources.
- Preserve document structure. Use suitable chunking strategies and metadata enrichment.
- Choose retrieval technology carefully. Evaluate vector, keyword, and hybrid search using real business questions.
- Enforce security at every stage. Implement authentication, document-level permissions, tenant isolation, and audit logging where required.
- Evaluate before scaling. Establish a representative test dataset and measure retrieval quality, answer faithfulness, and latency.
- Monitor after deployment. Track failures, user feedback, index freshness, model usage, and operating costs.
- Plan for continuous improvement. Revisit data sources, retrieval settings, prompts, and evaluation tests as business requirements change.
The most effective enterprise RAG architecture is not necessarily the most complex one. It is the architecture that meets the organisation's accuracy, security, performance, and business requirements without unnecessary operational complexity.
Enterprise RAG Use Cases Across Industries
Enterprise RAG can support different business functions by making organisational knowledge easier to retrieve and use.
Banking and financial services
Financial institutions can use RAG applications to search internal policies, product documentation, compliance material, and approved operational procedures.
Potential applications include:
- Compliance knowledge assistants.
- Internal banking policy search.
- Financial document analysis.
- Customer support assistance.
Sensitive financial information requires strict access controls, auditability, and human oversight for consequential decisions.
Healthcare
Healthcare organisations can use RAG to retrieve approved clinical guidelines, internal protocols, research material, and administrative documentation.
Potential applications include:
- Clinical knowledge retrieval.
- Healthcare policy assistants.
- Medical research discovery.
- Administrative document search.
Clinical use requires careful source validation and appropriate professional oversight. A RAG system should not replace qualified clinical judgement.
Manufacturing
Manufacturing businesses often maintain technical manuals, equipment documentation, maintenance records, and standard operating procedures.
RAG can help employees retrieve relevant information without searching through large collections of documents manually.
Potential applications include:
- Equipment troubleshooting assistants.
- Maintenance knowledge systems.
- Quality documentation search.
- Operational procedure assistants.
Retail and e-commerce
Retail businesses can connect RAG applications to product catalogues, support documentation, return policies, and internal knowledge bases.
Potential applications include:
- Product information assistants.
- Customer service copilots.
- Internal merchandising knowledge search.
- Returns and policy assistance.
Software and technology
Technology companies can use RAG to make technical information more accessible across engineering and support teams.
Potential applications include:
- Developer documentation assistants.
- API knowledge search.
- Internal engineering copilots.
- Technical support automation.
Enterprise RAG vs Fine-Tuning: What Should Businesses Choose?
RAG and fine-tuning are different approaches to improving an AI application's usefulness.
RAG gives a model access to relevant external information at query time. Fine-tuning changes model behaviour by training it further on a specialised dataset.
| Area | RAG | Fine-tuning |
|---|---|---|
| Main purpose | Provide relevant external knowledge | Adapt model behaviour |
| Updating business information | Update the knowledge index | May require additional training |
| Source citations | Can provide document-based citations | Does not inherently provide source citations |
| Private enterprise documents | Can retrieve approved documents | Training on private data requires additional controls |
| Best suited for | Knowledge retrieval and question answering | Style, format, task behaviour, and domain-specific patterns |
| Maintenance | Index and retrieval management | Model training and version management |
For many enterprise knowledge applications, RAG is a practical starting point because business documents can be updated without retraining the model.
Fine-tuning may be useful when an organisation needs specialised output formats, consistent task behaviour, or domain-specific response patterns.
Some applications benefit from combining both approaches. The decision should be based on the actual use case rather than assuming that one technique replaces the other.
How to Move from an Enterprise RAG Pilot to Production
A successful prototype does not automatically become a reliable enterprise application. Production deployment requires planning across data, infrastructure, security, evaluation, and user adoption.
A phased rollout can help manage the complexity.
Phase 1: Business discovery and use-case selection
Identify the business problem, intended users, data sources, expected outcomes, and success criteria.
Phase 2: Data and architecture assessment
Review document quality, system integrations, access permissions, hosting requirements, and technology choices.
Phase 3: Proof of concept
Build a limited RAG application using a representative dataset. Test retrieval quality, answer relevance, and user experience.
Phase 4: Security and evaluation
Validate access permissions, privacy controls, citations, failure handling, and performance against a defined evaluation dataset.
Phase 5: Production deployment
Integrate the solution with enterprise applications, configure monitoring, establish operational ownership, and roll it out to selected users.
Phase 6: Continuous optimisation
Use user feedback, evaluation results, and operational metrics to improve retrieval, data freshness, and response quality.
The timeline for each phase depends on the number of data sources, integration complexity, security requirements, and deployment environment.
How Spectrum Future Tech Helps Build Enterprise RAG Solutions
Building a production-ready RAG system requires more than selecting an LLM or vector database. Organisations need an architecture that connects their business information, preserves access permissions, retrieves relevant evidence, and supports ongoing evaluation.
Spectrum Future Tech provides Generative AI development services to help businesses design and develop AI applications around their data, systems, and workflows.
Our work can cover:
- Enterprise data assessment and preparation.
- RAG architecture design and implementation.
- Document processing and embedding pipelines.
- Vector and hybrid search integration.
- LLM integration and orchestration.
- Enterprise application and API integration.
- Access control and security considerations.
- Evaluation, monitoring, and optimisation.
Businesses still evaluating their AI opportunities can begin with an AI Readiness Audit to assess data readiness, identify suitable use cases, and establish implementation priorities.
The objective is to move beyond experimental AI demonstrations and build solutions that address real business requirements.
Final Thoughts
Enterprise RAG architecture provides a practical way to connect generative AI with the information organisations already own. It can make internal knowledge easier to access, improve document discovery, support employees, and create more context-aware business applications.
However, reliable results depend on the entire system—not just the language model. Data quality, document processing, retrieval relevance, permission enforcement, evaluation, and monitoring all influence the final experience.
Businesses planning an enterprise RAG implementation should begin with a clearly defined use case, assess their data environment, and validate the architecture with real questions before scaling.
With the right engineering approach, enterprise RAG can become a valuable foundation for secure, scalable, and useful AI applications.
Frequently Asked Questions About Enterprise RAG Architecture
1. What is enterprise RAG architecture?
Enterprise RAG architecture is a system design that connects large language models with organisational knowledge sources. It retrieves relevant business information and uses that context to generate more accurate, relevant, and source-supported responses.
2. What are the main components of an enterprise RAG system?
The main components include data connectors, document processing, chunking, embedding models, vector or search indexes, retrieval, reranking, LLM generation, access control, and evaluation and monitoring.
3. Why is RAG important for enterprise AI applications?
RAG helps AI applications use current and organisation-specific information that may not be included in a model's training data. It can also provide source references, support controlled knowledge access, and reduce reliance on retraining for frequently updated documents.
4. Which vector database is best for enterprise RAG?
There is no single best vector database for every enterprise. Pinecone, Weaviate, Chroma, pgvector, Elasticsearch, and managed cloud search services are possible options. Selection should consider scale, filtering, performance, security, integration requirements, and operational cost.
5. How does hybrid search improve RAG performance?
Hybrid search combines keyword matching and semantic vector search. It can improve retrieval when users ask natural-language questions but also need to find exact identifiers, product codes, technical terms, or policy references.
6. How can enterprise RAG prevent unauthorised data access?
Enterprise RAG should authenticate users, preserve document permissions in metadata, and apply access filters during retrieval. It should also support audit logging, permission updates, and security testing across different user roles.
7. What is the difference between RAG and Agentic RAG?
Traditional RAG generally follows a predefined retrieval and generation workflow. Agentic RAG introduces an orchestration layer that can break questions into subqueries, choose retrieval actions, and gather information from multiple sources when required.
8. Can enterprise RAG work with existing CRM and ERP systems?
Yes. RAG applications can connect to approved CRM, ERP, document management, database, and internal systems through APIs, connectors, and data pipelines. The integration approach depends on the source system, authentication model, and access requirements.
9. How do you measure the performance of a RAG application?
Common evaluation measures include retrieval precision, retrieval recall, context relevance, answer faithfulness, answer relevance, latency, cost per query, and access-control accuracy. Organisations should test the application using representative business questions and expected source documents.
10. How long does it take to build an enterprise RAG solution?
The timeline depends on the scope, data sources, document quality, integrations, security requirements, and deployment environment. A focused proof of concept may be completed much sooner than a multi-department production platform. A proper assessment is needed before estimating delivery time.